Yang You is a Presidential Young Professor at the National University of Singapore. He is on an early career track at NUS for exceptional young academic talents with great potential to excel. He received his PhD in Computer Science from UC Berkeley. His advisor is Prof. James Demmel, who was the former chair of the Computer Science Division and EECS Department. Yang You's research interests include Parallel/Distributed Algorithms, High Performance Computing, and Machine Learning. The focus of his current research is scaling up deep neural networks training on distributed systems or supercomputers. In 2017, his team broke the world record of ImageNet training speed, which was covered by the technology media like NSF, ScienceDaily, Science NewsLine, and i-programmer. In 2019, his team broke the world record of BERT training speed. The BERT training techniques have been used by many tech giants like Google, Microsoft, and NVIDIA. Yang You’s LARS and LAMB optimizers are available in industry benchmark MLPerf. He is a winner of IPDPS 2015 Best Paper Award (0.8%), ICPP 2018 Best Paper Award (0.3%), AAAI 2023 Distinguished Paper Award (0.14%), ACL 2023 Outstanding Paper Award (0.8%), and ACM/IEEE George Michael HPC Fellowship. Yang You is a Siebel Scholar and a winner of Lotfi A. Zadeh Prize. Yang You was nominated by UC Berkeley for ACM Doctoral Dissertation Award (2 out of 81 Berkeley EECS PhD students graduated in 2020). He also made Forbes 30 Under 30 Asia list (2021) and won IEEE CS TCHPC Early Career Researchers Award for Excellence in High Performance Computing. For more information, please check his lab’s homepage at https://ai.comp.nus.edu.sg/
《超大型人工智能模型训练与部署的高效技术》
嘉宾 : 尤洋 | 新加坡国立大学校长青年教授 潞晨科技创始人兼董事长
讲师介绍
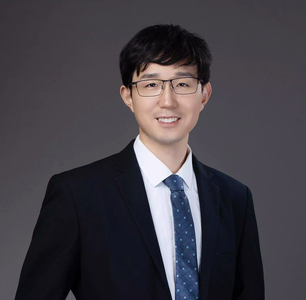
主题演讲嘉宾:尤洋
新加坡国立大学校长青年教授 潞晨科技创始人兼董事长
议题介绍
演讲:《超大型人工智能模型训练与部署的高效技术》
The Transformer architecture has improved the performance of deep learning models in domains such as Computer Vision and Natural Language Processing. Together with better performance come larger model sizes. This imposes challenges to the memory wall of the current accelerator hardware such as GPU. It is never ideal to train large models such as Vision Transformer, BERT, LLaMA, and GPT on a single GPU or a single machine. There is an urgent demand to train models in a distributed environment. However, distributed training, especially model parallelism, often requires domain expertise in computer systems and architecture. It remains a challenge for AI researchers to implement complex distributed training solutions for their models.
To solve this problem, we introduce a unified parallel training system designed to seamlessly integrate different paradigms of parallelization techniques including data parallelism, pipeline parallelism, multiple tensor parallelism, and sequence parallelism. Our system aims to support the AI community to write distributed models in the same way as how they write models normally. This allows them to focus on developing the model architecture and separates the concerns of distributed training from the development process. Our system is able to achieve 2x speedup over state-of-the-art distributed systems for GPT model training.
关注主办方(InfoQ)
联系我们
交通指南
北京富力万丽酒店

 京公网安备 11010502039052号 | 产品资质


微信咨询

电话咨询
联系电话:18518913363

微信联系我们